We build the infrastructure and models that make AI run at the speed of reality.


Everything humanity is about to build runs on a limited number of chips.
Introducing
Decart Optimization Stack.
Frontier optimization technology that extracts up to 100× more performance from the chips you already run.
 Google TPUs
 AWS Trainium
 Nvidia GPUs

Hardware agnostic
Run optimized workloads across every major chip architecture. Your workload shouldn't care what it runs on.

Peak hardware performance
Extract more from the compute you already have. No new racks. No new contracts. New ceiling.

Ultra-fast inference
Frontier models at lower latency and higher token throughput. Intelligence at the speed of reality.
Deploy the Live AI layer
Contact usOne stack powers every layer of Live AI.
DOS powers Decart's proprietary models as well as external LLMs and agentic workloads.
World Editing Model
Edit reality as it streams. Transform people, objects and environments live.
World Generation Model
Create live, interactive worlds that evolve instantly, with every action.
What Live AI unlocks
Explore what becomes possible when models can edit, generate, and respond live.
Math to Matter
New research, launches, and experiments.
 Read more →
Lucy 2.5: Raising the Bar for Live AI
Higher-quality edits, physically-aware VFX, stronger temporal consistency, and even lower latency, all generated live at 30 FPS.
 Read more →
Startup Makes Switching AI Chips Easier—and Nvidia Is a New Investor
 Read more →
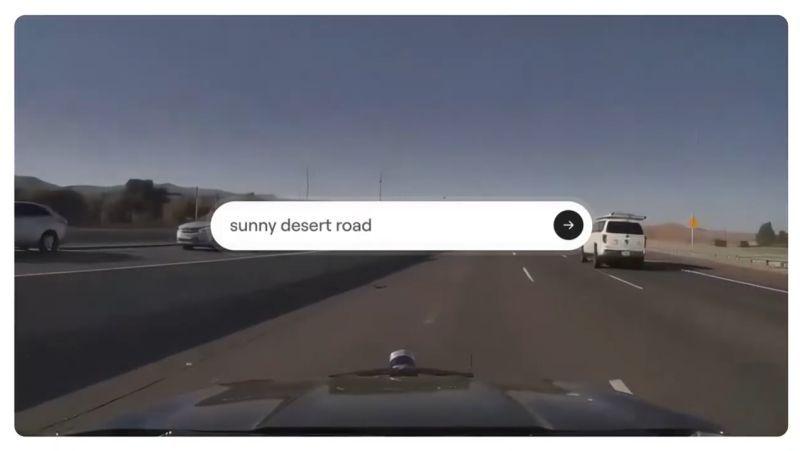
Decart’s new world model can simulate hours of photorealistic driving — with some caveats
 Read more →
Introducing Oasis 3: First Interactive World Model for Physical AI
Today, we’re introducing Oasis 3 — Decart’s flagship interactive world model, a major step towards a future where robots are an everyday reality.
 Read more →
Decart Raises $300M: Tech Leaders Back the Company as Both Customers and Investors
With funding led by Radical Ventures, Decart is building the infrastructure layer for the next generation of low-latency AI systems, through three product lines: DOS, an ultra-optimized inference and training stack that enables agents and reasoning models to run smarter and faster; and the models Lucy, its World Model for Immersive Experiences; and Oasis, its World Model for Physical AI – both powered by DOS. Today, we’re also announcing DOS 2.0, with new versions of Lucy and Oasis launching in the coming weeks.
 Read more →
What if video editing had a volume knob?
Text-driven video editing lets you describe what to change. But what about how much? We introduce Adaptive-Origin Guidance (AdaOr), a method that turns edit intensity into a smooth, continuous slider.
 Read more →
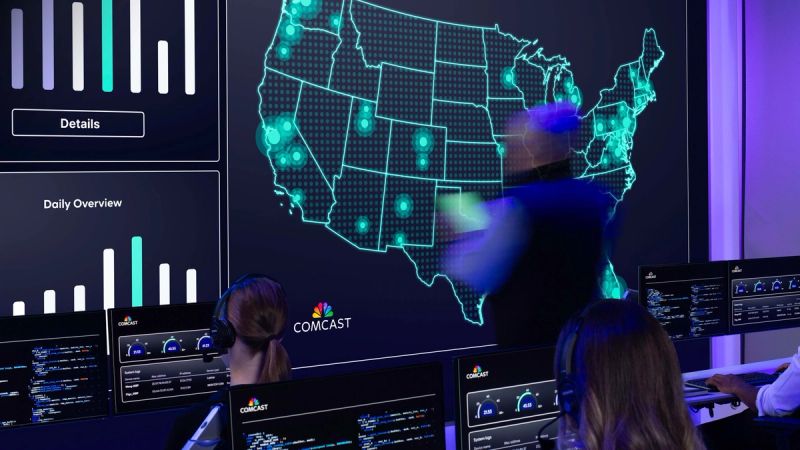
Comcast to Accelerate Next-Generation AI Applications Using NVIDIA Infrastructure at the Network Edge
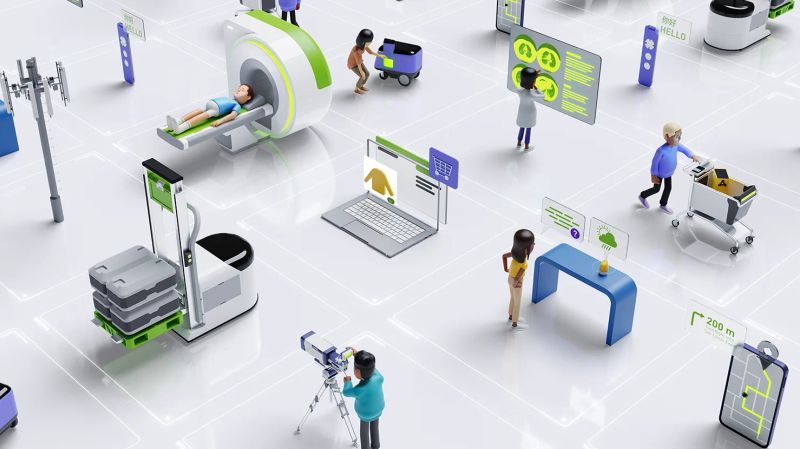
Comcast today announced a groundbreaking initiative to bring AI processing, using NVIDIA GPUs, closer to customers than ever before to accelerate the development of next-generation AI applications across America.
 Read more →
Building the AI Grid with NVIDIA: Orchestrating Intelligence Everywhere
AI-native services are exposing a new bottleneck in AI infrastructure: As millions of users, agents, and devices demand access to intelligence, the challenge is shifting from peak training throughput to delivering deterministic inference at scale—predictable latency, jitter, and sustainable token economics.
 Read more →
Closing the Latency Gap: Decart Is Helping Shape the AI Grid
Decart is collaborating with Comcast to move high-performance inference to the edge powered by Nvidia GPUs – enabling sub-35ms generative AI experiences.
 Read more →
Oasis: A Universe in a Transformer
Powered by our Oasis video model, your actions shape the environment in real time.
 Read more →
This AI-generated open-world demo may represent the future of real-time video generation
The interactive demo, Oasis, is created from clips and keyboard inputs alone- it stands as the first real-time, interactive, generative AI video model.
 Read more →
Why Sequoia’s Shaun Maguire is Betting on a Year-Old AI Video Startup
Sequoia partner Shaun Maguire has risen to prominence over the past year for his friendship with Elon Musk..
 Read more →
Introducing Lucy 2: SOTA realtime world transformation model
Today, we’re releasing Lucy 2.0 — a real-time world transformation model that shifts high-fidelity video editing from offline rendering to live interaction. This opens up an unlimited set of possibilities ranging from character swaps and product placement to high-fidelity real-time data augmentation and simulation for robotics.
 Read more →
Sequoia-backed Decart raises $21M in Seed funding
The Israeli startup has built an AI infrastructure platform that enhances the efficiency of AI models, offering faster and more reliable training as well as real-time inference.
 Read more →
The startup Decart became profitable within three months
Dr. Dean Leitersdorf and Moshe Shalev succeeded in securing a $21 million seed round from Sequoia and Oren Zeev. (Hebrew)
 Read more →
This AI Warps Live Video in Real Time
A startup called Decart has developed an AI model that can transform live footage. The results are mind-bending—and poised to take over streaming.
 Read more →
Partnering with Decart: The Future of AI-Generated Experiences
A breakthrough in video inference offers a sneak peek at the next frontier.
 Read more →
Building Living Characters With Decart and ElevenLabs
Decart syncs the lips. ElevenLabs gives them soul. Together, they turn digital avatars into living characters.
 Read more →
Decart nabs $32M to build AI tech and ‘open world’ apps
A young startup that emerged from stealth less than two months ago with big-name backers and bigger ambitions is returning to the spotlight.
 Read more →
Decart raises $100 million at a $3.1 billion valuation
Exclusive: Decart raises $100 million at a $3.1 billion valuation, chasing the future of real-time creative AI
 Read more →
Decart's AI simulates a real-time, playable, open-world demo
Decart, an Israeli AI company that emerged from stealth today with $21 million in funding, has released what it's claiming is the first interactive "open-world" model.
 Read more →
Decart’s New Lucy 2 Generative AI Video Model Pushes Generative Video Into Real Time
 Read more →
'Wow, This Is Happening Fast': Why Elon Musk Is Excited About Game-changing Israeli Startup
Just four months after a giant seed round, Decart has raised another $32 million. Investors – and the gamers community – are drawn to its generative game model.